
Salesforce AI Analysis has been constructing Launa-Omni, a voice mannequin that holds real-time, two-way conversations. The newest analysis outcomes got here on this week, and this put up covers what we constructed and the way it scores.
Voice is the oldest interface individuals have, and it’s the hardest one to get proper when a dialog has to finish in actual work. Constructed for the calls for of enterprise work, Launa-Omni goals to make speaking with AI really feel extra direct whereas preserving the accuracy and visibility groups must belief a solution and act on it.
Launa-Omni is, true to its identify, an omni voice mannequin. Its core is a textual content mannequin retrofitted for audio, so speech and language share a latent house. Exterior that core mannequin, an in-house-trained text-to-speech (TTS) mannequin produces the spoken reply. Though generalizable, Launa-Omni was developed and skilled for experiences in Salesforce and Slack, the place conversations must really feel pure and enterprise duties demand accuracy and dependable instruction following.
The mannequin is considerably smaller than different main voice fashions, and we now have fastidiously balanced voice high quality with the velocity and price of serving conversations at enterprise scale.
Constructed for work
An excellent dialog has to carry as much as actual work.
Enterprise voice brokers want to reply promptly, deal with exact data, and make their habits seen and steerable. These qualities matter when a dialog results in a buyer report, a workflow, or a call.
- Responsive
Launa-Omni’s real-time harness detects speech and determines when an individual’s flip is full, serving to the system reply promptly and hold conversations shifting.
- Correct
Launa-Omni will be custom-made and fine-tuned to raised deal with named entities, dates, alphanumeric IDs, and {industry} jargon.
- Interpretable
Launa-Omni produces a textual content response earlier than something is spoken, so the reply is seen in the mean time it’s shaped and groups can examine and proper it. That retains a system that acts on what it heard underneath human course.
The Method: How we give AI a voice
To grasp how Launa-Omni works, we first must share the way it doesn’t work. Earlier voice programs made speaking with AI attainable. And later, they had been improved to appear extra pure. Every strategy introduced tradeoffs in responsiveness, serving value, and the way a lot of the response groups can examine—selections that formed Launa-Omni.
Earlier approaches
Most voice programs in the marketplace at present comply with one in every of two strategies:
1. Cascaded voice programs
Separate speech recognition, language, and speech technology fashions course of every flip in sequence. Their handoffs hold the textual content seen, however can lose particulars from the unique voice and add pauses that make replies really feel gradual and stilted.
2. Speech-to-speech fashions
A single mannequin takes speech in and produces speech out, usually making the alternate smoother and extra pure. The tradeoff will be increased serving value and fewer visibility into how a reply was shaped, making errors tougher to examine and proper.
Launa-Omni’s strategy
A voice system constructed for work
Launa-Omni brings speech and language collectively in a single audio-adapted textual content mannequin, then provides a separate in-house TTS mannequin to talk the reply. The textual content response stays seen and simpler to steer.
That construction comes from a deliberate selection about the place transcription belongs. As soon as speech turns into textual content earlier than the mannequin causes about it, most of what makes speech helpful is already gone. Tempo, hesitation, and emphasis all carry that means {that a} transcript can not maintain, and a cascaded system discards each little bit of it on the first handoff.
Evaluations: Launa-Omni’s outcomes
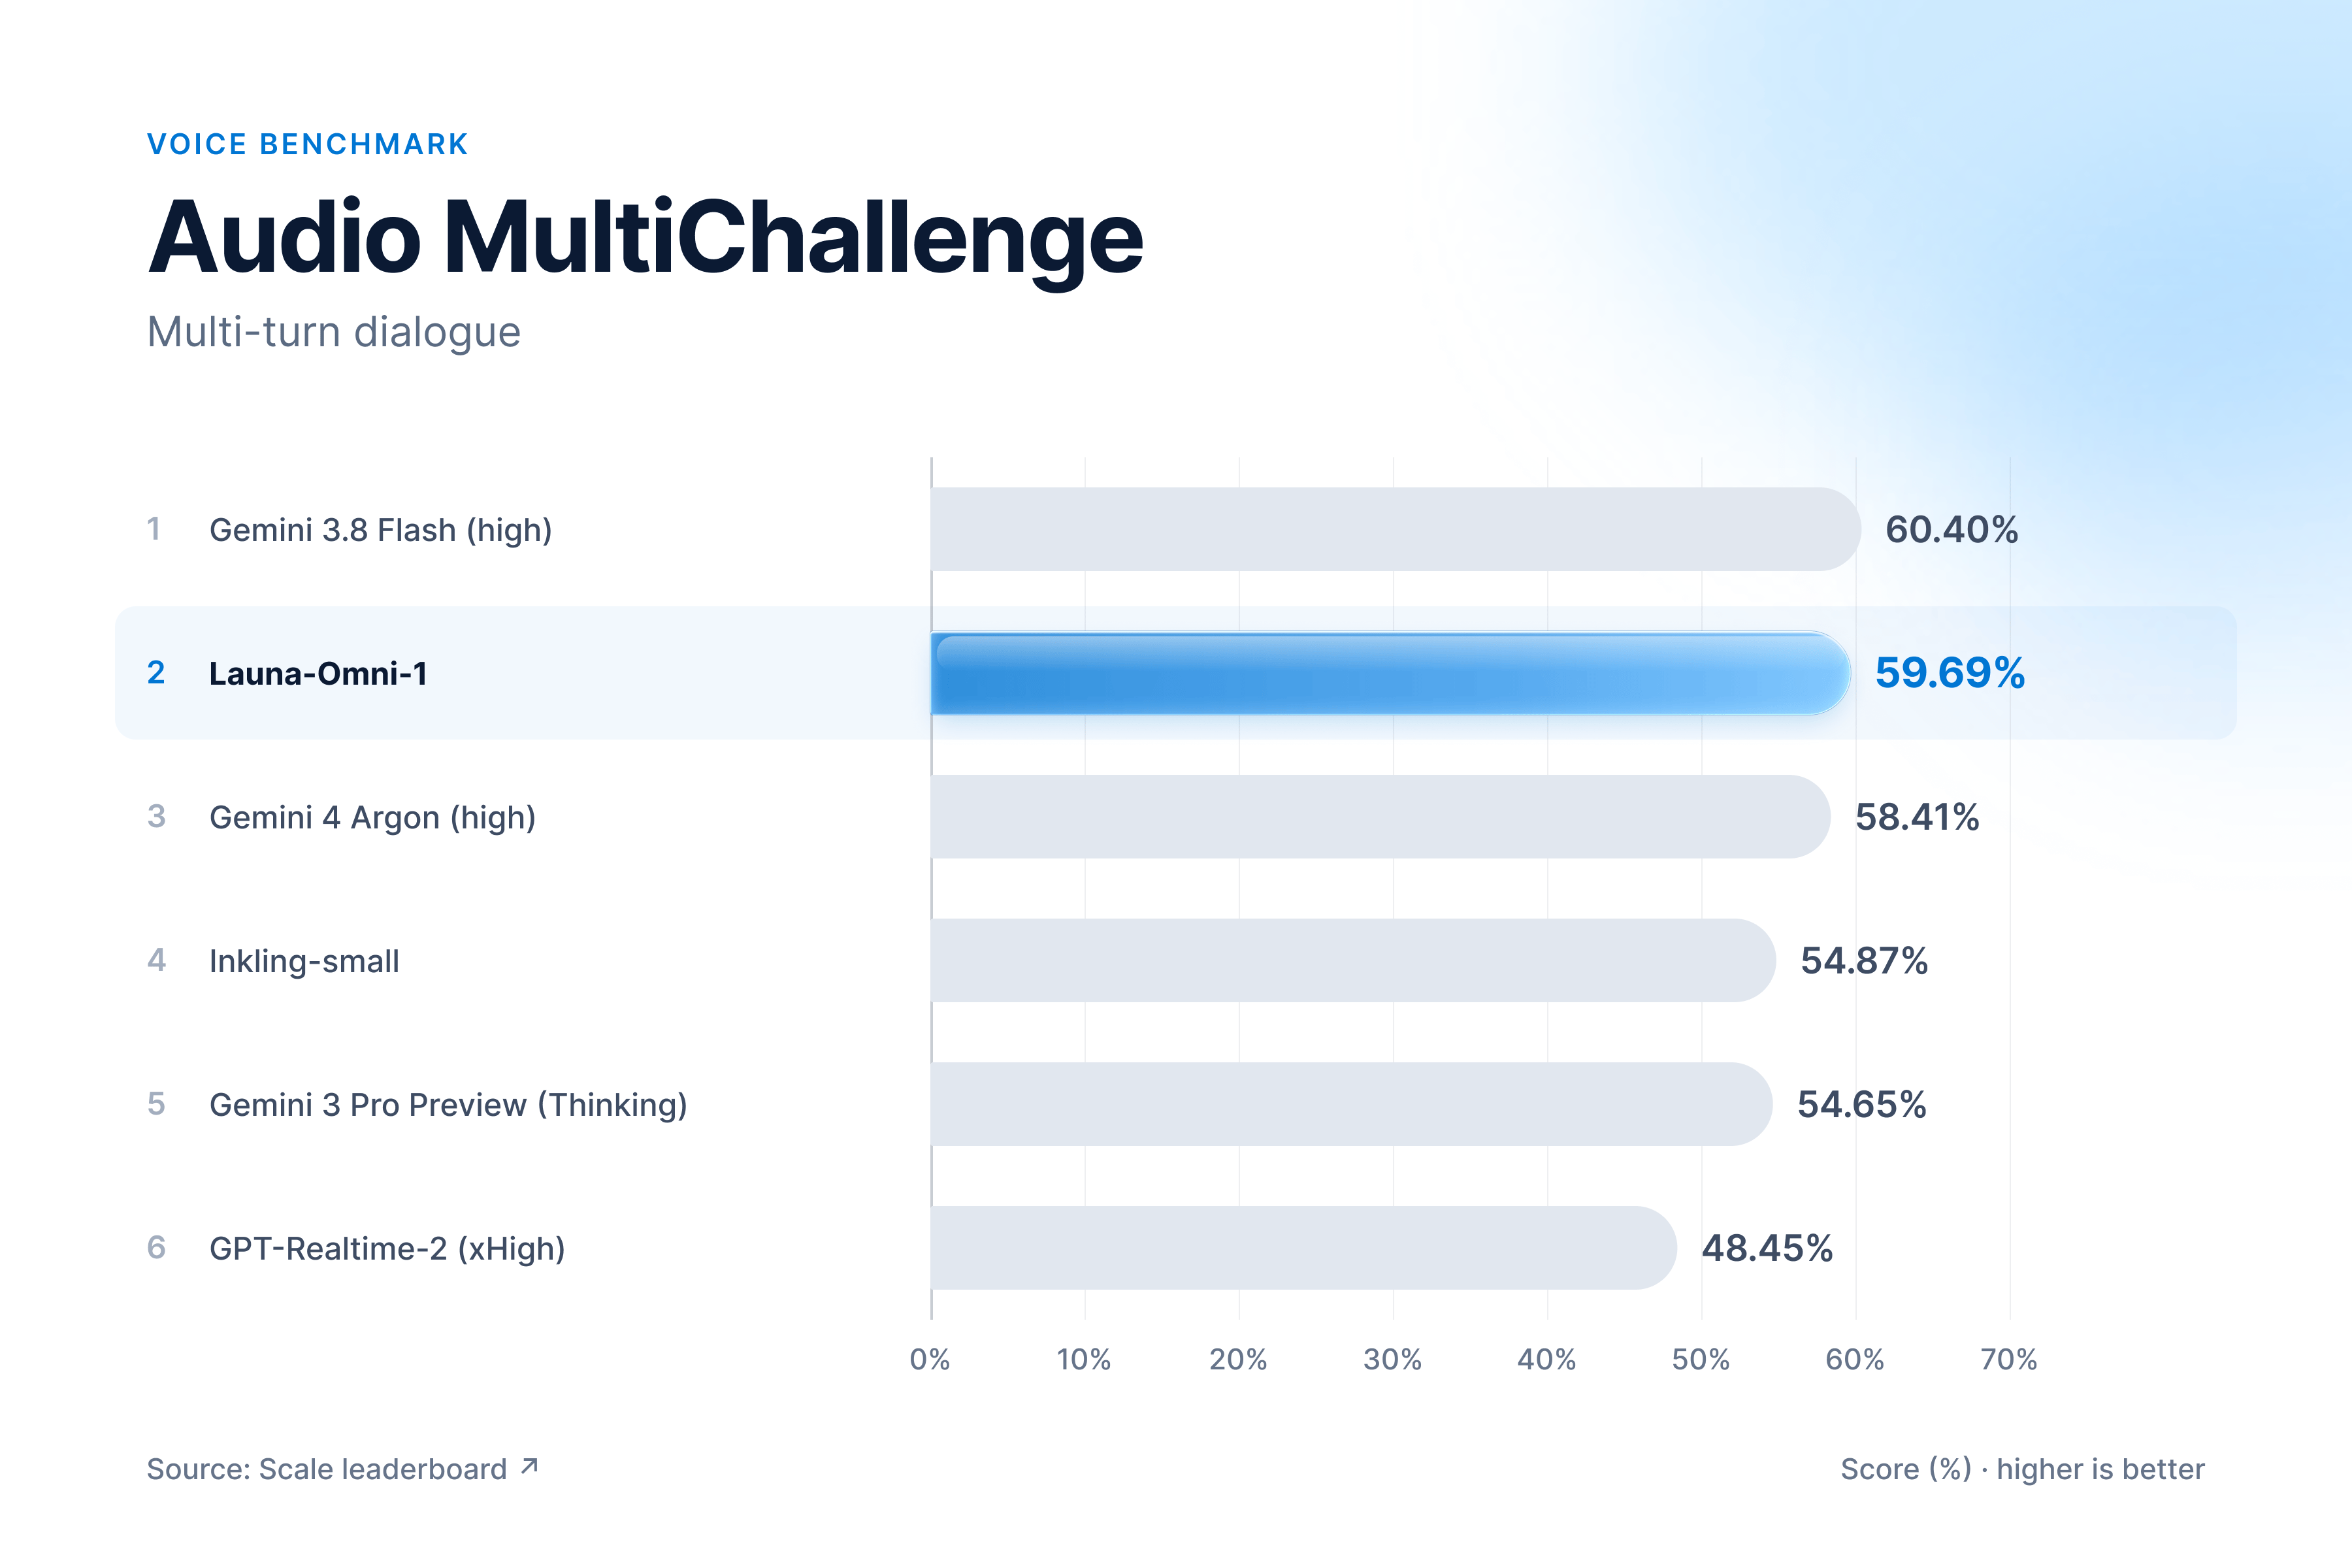
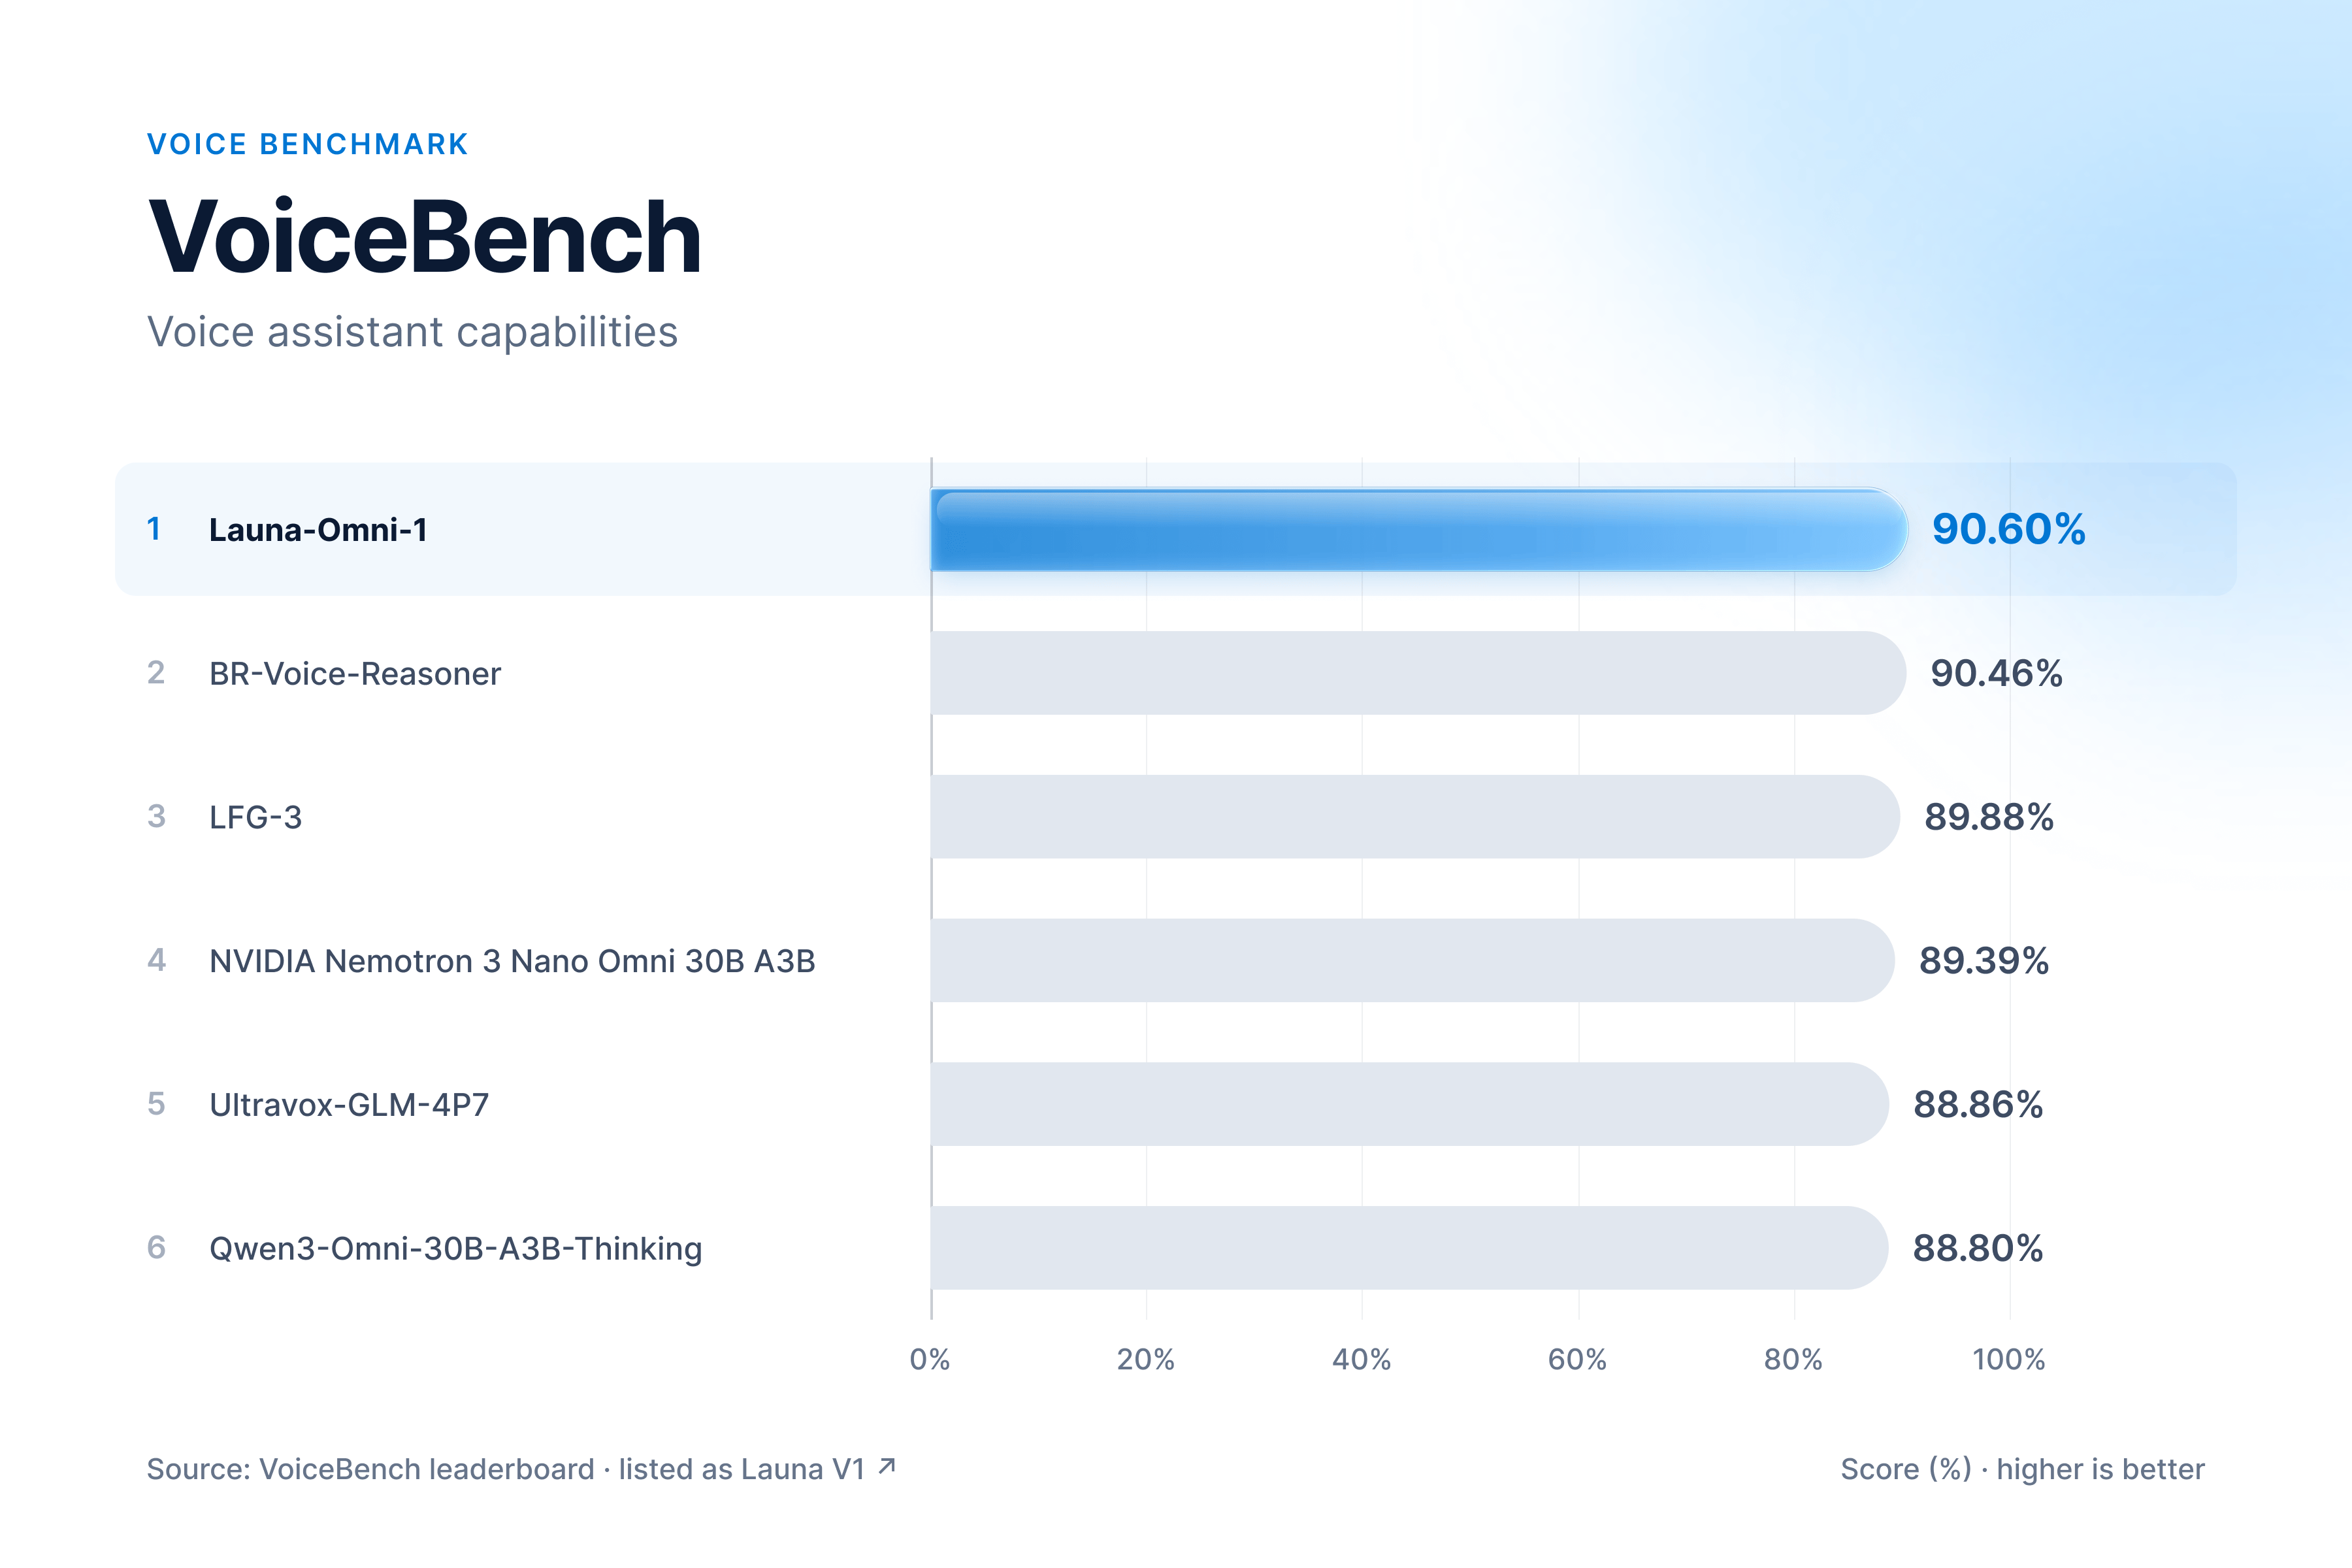
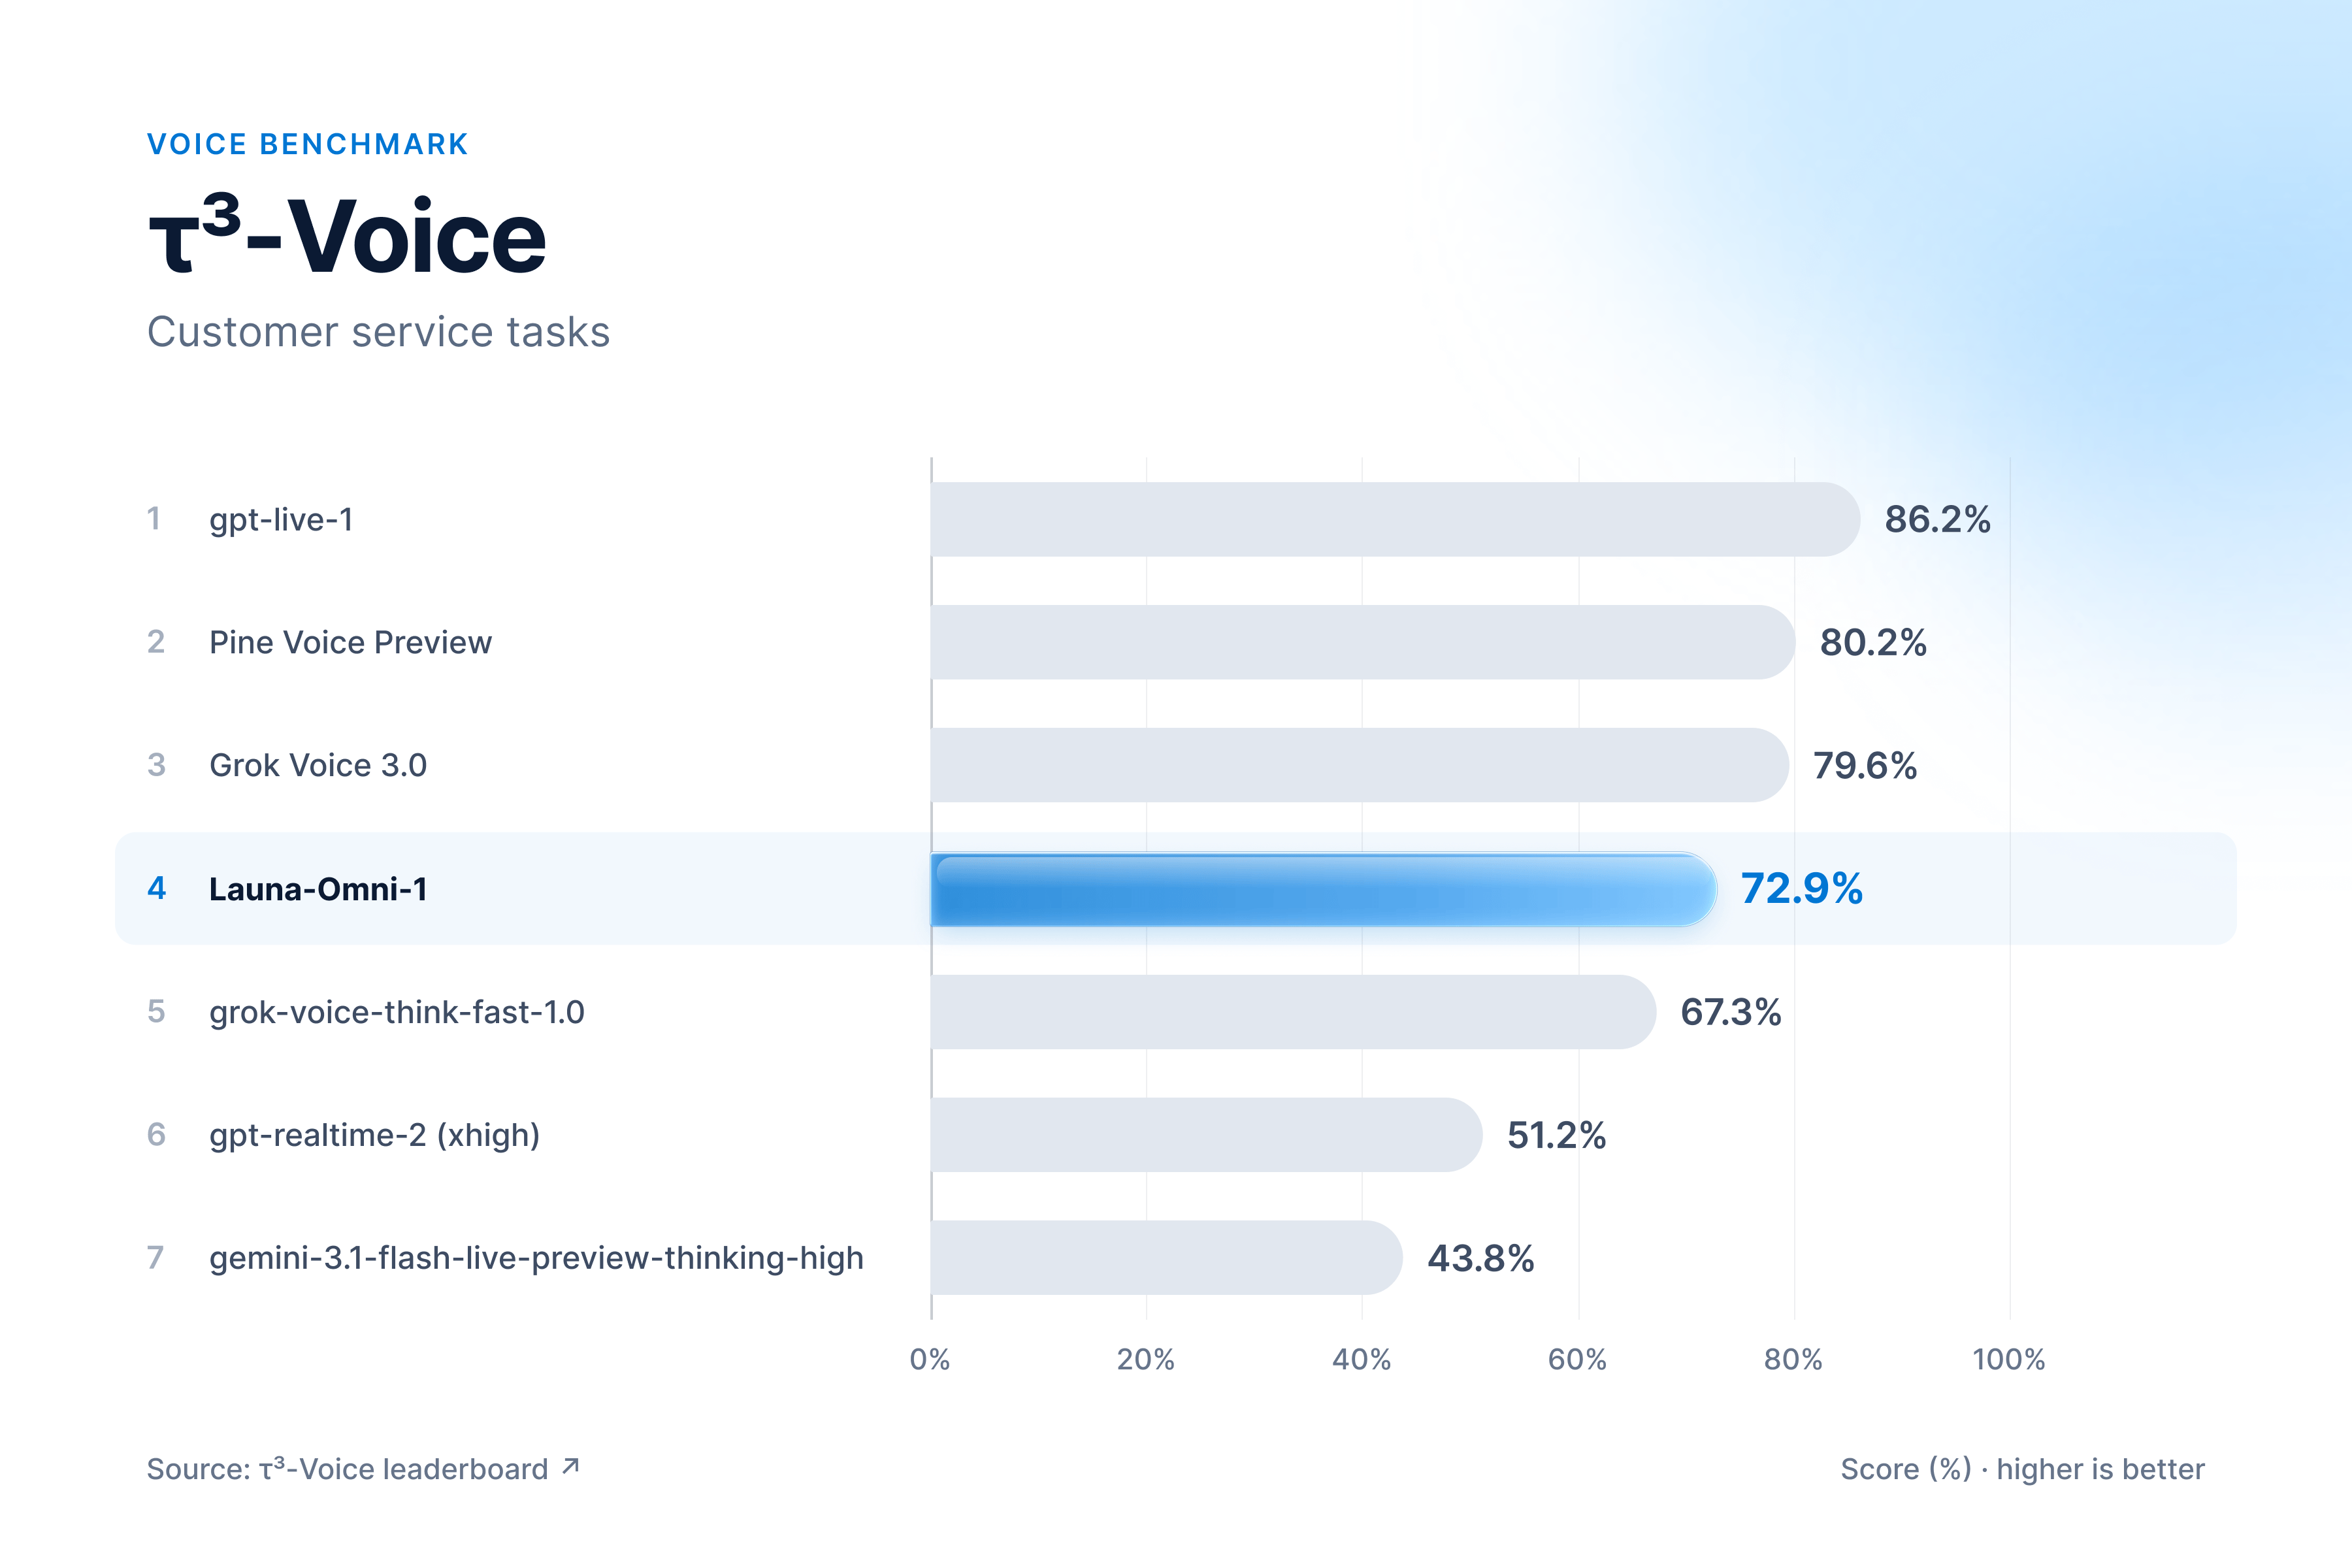
Launa-Omni reveals aggressive outcomes throughout spoken instruction following, multi-turn dialogue, and customer-service duties—three capabilities that matter when voice brokers transfer from dialog to work. The mannequin is aggressive in opposition to a number of considerably bigger in dimension. Right here’s the way it stacks up within the leaderboards:
The fitting mannequin for the dialog. The fitting mannequin for the work.
Some requests want longer reasoning, search, or an agent that may perform a posh process. Launa-Omni will be paired with a frontier mannequin behind the expertise, maintaining voice as the purpose of interplay whereas deeper work is routed to the system finest suited to it.
That flexibility is a deliberate design selection, as voice turns into the best way individuals direct their digital labor. Getting it proper means programs quick sufficient to really feel pure and accountable sufficient to belief with actual work. That mixture is what we at Salesforce AI Analysis are constructing towards.
Slack customers can already expertise a simplified model of this mannequin in its speech-to-text dictation function, Slackbot Voice Dictation. Study extra about our proprietary AI fashions and the way they’re reworking our merchandise and our clients’ enterprise companies at Salesforce AI Analysis. It’s also possible to obtain a subset of our industry-leading fashions for analysis functions on Hugging Face.